

Most crypto marketing teams think "do we show up in ChatGPT" has a yes or no answer. It doesn't, and the sooner you stop looking for one, the sooner you can measure something useful.
The metric this piece is built around replaces that yes-or-no instinct with six numbers, tracked by platform and by the kind of question being asked. Get the method right and it tells you whether Gemini is quietly recommending a competitor on fee comparisons while Claude can't name you at all on safety questions.
Get it wrong, and you've just built a prettier vanity metric with a crypto label stuck on the front, one number standing in for six different questions.
That's the kind that looks great in a board deck and tells you nothing about what to actually fix. This piece is the method, not the marketing version of it.
What Share of Model Voice Measures
The underlying metric is the proportion of relevant AI answers in which your brand appears, measured against a defined set of competitors, across a defined set of prompts. That is the whole definition, and almost every part of that sentence is where the vendor blogs go soft.
"Relevant answers" means the subset of your prompt panel where a brand in your category could plausibly appear. Running a prompt your product has no business answering and counting its absence as a loss is not measurement, it's self-sabotage. The "defined competitor set" matters just as much: five rivals gives a different number to fifteen, and neither is wrong, they're just not comparable to each other.
The part most guides skip entirely is that appearing is not one thing. A mention is the model saying your name. A citation is the model linking to or attributing specific information to your site, the behavior Anthropic's own platform documentation describes when Claude's search-result content blocks attach a source to a claim. A recommendation is the model actively presenting you as an option worth choosing, which is a different act again and the one that actually moves a user.
Collapse those three into one percentage and you've thrown away the one distinction that tells you what to do next. A project with high mentions and zero citations has an authority problem. A project with citations but no recommendations has a positioning problem. Same input data, two completely different fixes.
Why One AI Screenshot Is Not a KPI
A screenshot of ChatGPT naming your protocol is a nice Slack message. It is not evidence of anything repeatable, because the system producing it is stochastic by design. Ask the same question twice and the model can return two different answers, cite two different sources, and name a different brand first, same model, same day.
That isn't a bug you caught at an unlucky moment. Research on generative engine optimization found that engines cite different source ecosystems and vary run to run, which is precisely why visibility has to be measured as a vector across repeated prompts and periods rather than captured once and filed as proof.
Prompt phrasing moves the output too, and search mode compounds it further. "Best DEX for low fees" and "cheapest place to swap tokens" might pull from different retrieval paths entirely, even though a human reads them as the same question, and a model answering from its own training versus one actively grounding in live web search can surface entirely different brands because it genuinely isn't running the same process underneath.
Then there's the moving target problem. Model updates happen on each vendor's own schedule, not yours, and a provider's retrieval or ranking change can shift your visibility overnight with no announcement attached to it. A number from March tells you about March, nothing more. Treat one favorable run as a trend and you'll chase noise instead of signal, with no idea which of the real levers, content, authority, structured data, actually moved anything.
This is the case for generative engine optimization for crypto as a discipline generally: it isn't a one-off audit, it's a measurement habit, because the thing you're measuring refuses to sit still.
Build a Representative Crypto Prompt Panel
A prompt panel is the set of questions you'll run, repeatedly, to generate your scorecard. Build it badly and every metric downstream inherits the bias.
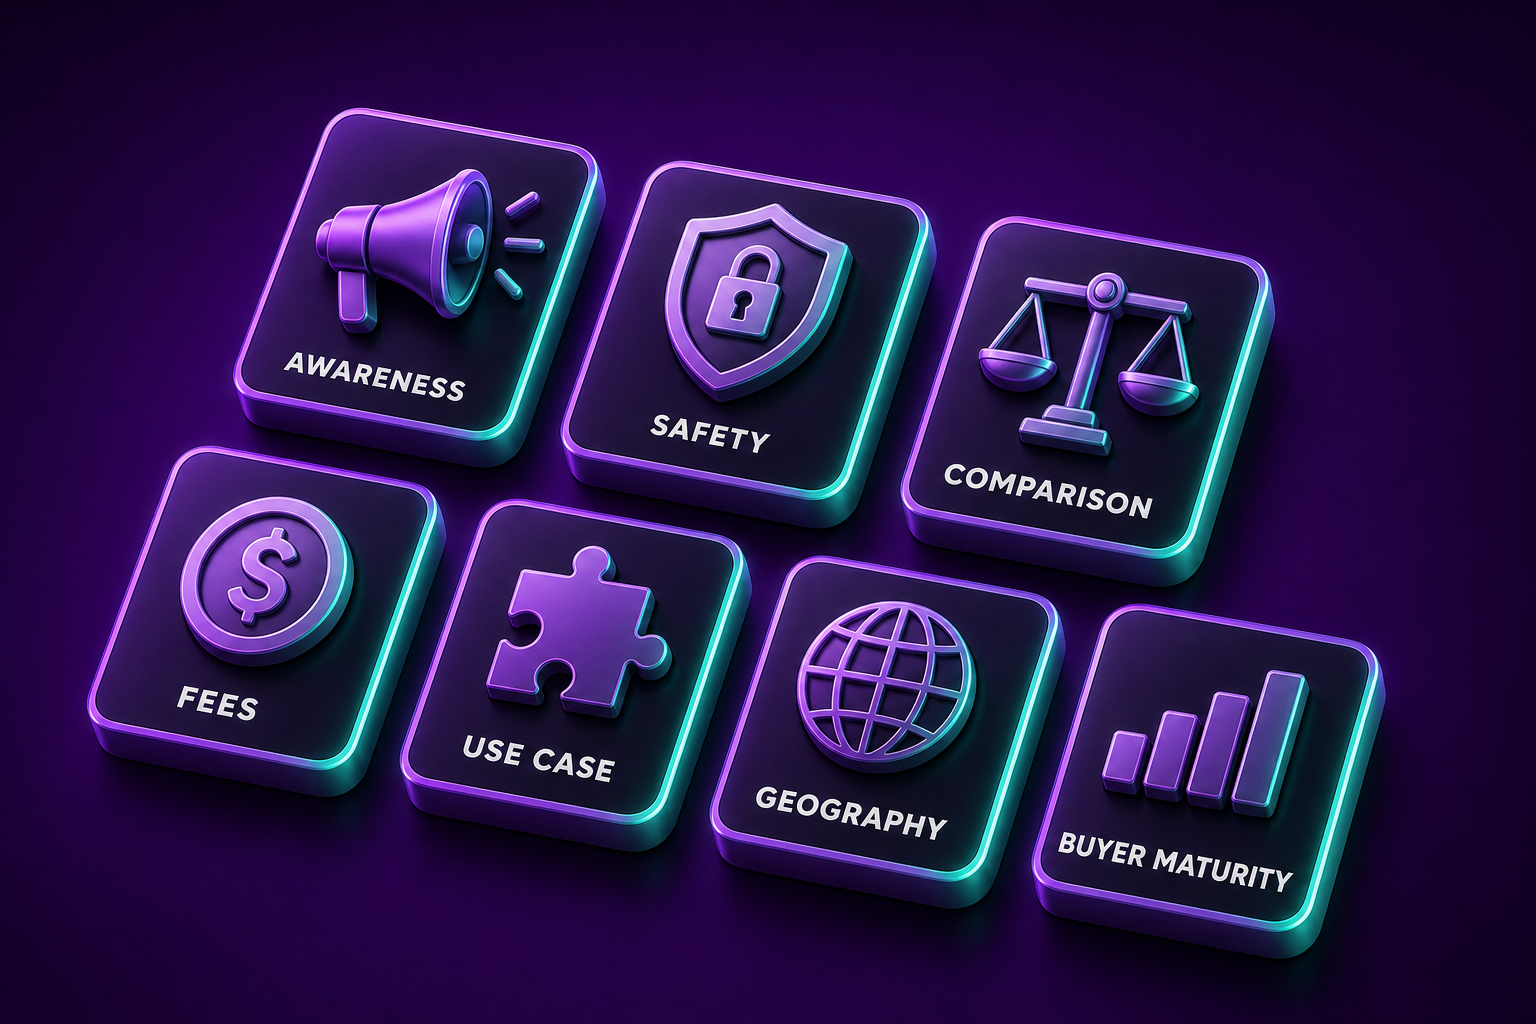
Start by segmenting prompts into categories that map to how people actually research a crypto product, not how your marketing deck describes it. Awareness prompts are broad category questions, the kind a newcomer types before they know your name exists. Safety prompts ask whether something is legitimate, audited, or a scam, and crypto carries far more of these than most categories ever will.
Comparison prompts pit you against named rivals. Fee prompts ask about cost structure specifically, because fee answers get invented more often than almost anything else in this category. Use-case prompts describe a job to be done rather than a product name.
Geography prompts matter because availability, regulation, and even which exchanges a model recommends can shift by region. Buyer-maturity prompts separate a first-timer's question from a sophisticated user's due-diligence question, because the two rarely pull the same sources. None of these categories are optional; skip safety prompts for a DeFi protocol and you've built a panel that misses the exact question most likely to cost you a user.
Here's an example of how that panel might be structured for a DeFi lending protocol:
| Category | Example Prompt | Why It's Tracked |
| Awareness | "What is a lending protocol in DeFi?" | Tests category-level visibility, no brand expectation |
| Safety | "Is [protocol] safe to use?" | Highest reputational risk if the answer is wrong |
| Comparison | "[Protocol] vs Aave, which is better?" | Direct competitive framing |
| Fees | "What are the fees on [protocol]?" | Fees get hallucinated often, high accuracy risk |
| Use case | "Best place to borrow against ETH" | Product-agnostic, tests if you surface at all |
| Geography | "Can I use [protocol] in the US?" | Availability answers vary sharply by region |
| Buyer maturity | "[Protocol] smart contract audit history" | Due-diligence language, sophisticated user intent |
Example: a six-category crypto prompt panel built for a DeFi lending protocol.
There's no universal number of prompts that makes a panel "representative". What matters is that it covers every category your real users actually ask about, that you disclose the panel size and composition when you report results, and that you revisit it as your product and the questions around it change.
A panel built in January for a lending protocol is already stale by the time you ship a new collateral type. Treat the panel itself as a living document, reviewed on the same cadence as the scorecard it feeds.
The Six-Metric Crypto SoMV Scorecard
A single percentage can't tell the difference between a model that ignores your brand and one that actively warns users away from it. Those are not the same failure, and they don't take the same fix, which is why the metric should be reported as six separate numbers rather than one blended score.
Mention share is the simplest: the proportion of relevant answers where your brand name appears at all, in any context, positive or negative. It's the floor metric, the one closest to what most tools already report, and the least informative on its own.
Citation share counts how often the model links to or attributes information specifically to your own domain or documentation. A mention with no citation means the model knows your name from somewhere but isn't treating your own site as the source of truth about you.
Recommendation share is narrower still: the proportion of answers where you are explicitly presented as an option worth choosing, not just named in passing. This is the number closest to commercial impact, and the one vendor dashboards most often conflate with simple mentions.
Prominence measures where in the answer you show up, first paragraph versus a footnote three names deep, because position changes how much a reader actually registers the mention.
Sentiment scores whether the framing around your name is positive, neutral, or negative, which matters more in crypto than in almost any other category given how fast "unaudited" or "under investigation" language can attach to a brand. Factual accuracy checks whether what the model says about you, your fees, your audit history, your chain, your token model, is actually correct.
This is the metric every generic SoV framework skips, and in crypto it's arguably the one with the highest reputational stakes. A model confidently inventing a fee structure or misstating your audit status is a materially different problem than simply being absent from an answer, and a blended percentage will never show you which one you have.
Score each metric per platform and per prompt category. A brand can run high mention share and near-zero factual accuracy on fee questions specifically, and that pattern only becomes visible once you stop averaging it away.
Normalize Results Across ChatGPT, Gemini & Claude
Report each model separately before you ever produce a combined number. The three platforms don't retrieve, rank, or cite information the same way, so an aggregate can hide a real weakness in any one of them.
Google's Gemini API documentation describes an opt-in grounding tool that handles search, processing, and citation as one automated workflow, returning inline citation annotations tied to the retrieved source. Anthropic's web search tool for Claude works through search-result content blocks with citations attached by default, built so a user can verify the answer against its source.
Different triggers, different retrieval paths, different citation presentation. A project citing well on Gemini because grounding happens to be enabled for that query type tells you nothing about whether Claude's web search tool is even being invoked for the same question.
Build a weighted portfolio view only after the three sit side by side. Weight it by where your actual users ask questions. If your audience skews toward ChatGPT for research and Gemini for quick lookups, weight accordingly, and say so in the report rather than let a flat average imply parity that doesn't exist.
Add Repeat Runs and Confidence Bands
Run every prompt through every platform more than once across a defined window, and report the range alongside the average. A recommendation share of 40% built from a single pass through each prompt is a guess dressed up as a statistic.
The academic research behind this field exists precisely because single-shot measurement doesn't hold up. The GEO benchmark paper treats visibility as something to be tested across a diverse query set rather than captured in one pass, and found that optimization techniques could lift visibility by up to 40%, with the effect varying by domain, exactly the kind of movement that single-run measurement would miss or misattribute entirely.
Disclose five things alongside every number: the date the run happened, the model and version where known, the search mode (automatic, triggered, or grounding enabled), whether the account was logged in or anonymous, and the geography the query was run from. Each of these can shift the answer, and a report that doesn't name them is a report nobody downstream can reproduce or trust.
This is also where the temptation to publish a universal benchmark should die. There is no verified "25% is good" figure for this metric, in crypto or anywhere else, because the number only means something next to a comparable category, a fixed prompt set, a fixed model mix, a fixed geography, and a fixed measurement window. Anyone quoting a bare percentage without naming all five of those is quoting a marketing line, not a measurement.
Connect Model Voice to Business Outcomes
This exercise earns its place on a dashboard the moment someone can tie it to something the business already tracks: qualified visits, sign-ups, wallet connections, developer activity, retained users. Tag AI referral traffic distinctly in analytics, the way you'd already tag a paid campaign, and watch whether weeks with higher recommendation share also show higher assisted conversions in that referral segment.
That word, "assisted", is doing real work. A visitor arriving after an AI recommendation and converting a week later is a correlation worth watching, not proof the recommendation caused the conversion. Dozens of other variables moved in that same week.
Report the relationship as exactly what it is, a pattern worth tracking over time, and resist the pitch-deck temptation to call it attribution. The same discipline applies to any channel; it's the reason crypto social media management reporting has moved away from impressions and toward tagged referral traffic over the past couple of years.
What's genuinely useful here is the concentration data from outside general marketing. DefiLlama Research tested 120 outputs from 30 prompts across four models, Claude Opus 4.7, GPT-5.4, Gemini 3 Flash, and Qwen 3.6 Plus, in English and Mandarin. Three exchanges, Binance, OKX, and Bybit, appeared in every single output. No run omitted any of the three.
That is a mention-share ceiling effectively locked in before most other brands get a look in, and it's the clearest evidence available that model visibility concentrates hard at the top of a category. It also shows exactly why the per-model, per-prompt breakdown matters: a single blended number across four models and two languages would report "high AI visibility for exchanges" and bury the fact that three names are absorbing all of it.
For a project outside that top tier, the business question isn't "how do we hit 100%", it's "where in our funnel does being absent from that answer actually cost us a user". That's a question only tagged outcome data can answer.
Reporting Cadence and Decision Rules
Run the full scorecard monthly, and treat the first month as a baseline, not a verdict. You cannot call a number good or bad until you have at least one comparison point behind it.
From month two, set change thresholds in advance rather than reacting to whatever moved. A reasonable starting rule: flag any metric that shifts more than one confidence band from its baseline, and investigate before you act. Set a separate, harder trigger for factual accuracy specifically, because an accuracy drop is a different kind of emergency to a mention-share dip. If a model starts stating a wrong fee structure or a false safety claim, that's a same-week content and outreach response, not a line item for next month's report.
Here's an example of how decision rules might be structured:
- Mention or citation share drops across two consecutive monthly runs on the same platform: treat as a content and authority gap, prioritize updating or publishing documentation the model can retrieve.
- Recommendation share stays flat while mention share rises: treat as a positioning problem, the model knows you exist but isn't choosing you, which is a messaging fix rather than a visibility fix.
- Sentiment turns negative on a specific prompt category: treat as urgent, trace the source the model is citing and address it directly.
- Factual accuracy fails on fees or safety specifically: escalate immediately regardless of overall trend, this is the highest-stakes failure mode in the whole scorecard.
Keep the reporting cadence boring and consistent. The value of this exercise comes from the twelfth month looking directly comparable to the first, not from reinventing the method every quarter because last month's number was disappointing.
Conclusion
The six-metric scorecard is a diagnostic portfolio, not a single number you can put in a pitch deck and declare victory. Treat it that way, reported per platform and per prompt class, with run-to-run variance disclosed, and it tells you precisely where your visibility problem actually sits, which is the only version of this exercise worth building a strategy around.
Here's the honest limitation: Coinpresso does not hold a published, proprietary cross-model benchmark the way DefiLlama Research's exchange study does, and claiming otherwise would be exactly the kind of invented authority this piece argues against. What we can do is build that baseline for your project specifically, your prompt panel, your competitor set, your platforms, run properly and repeated properly from month one.
Check this tonight: pick five prompts a real customer would ask about your category, run each through ChatGPT, Gemini, and Claude once, and see whether you can tell a mention from a citation from a recommendation in what comes back. If you can't tell the difference in five minutes of reading, your current measurement, if you have any, isn't actually measuring what it claims to.
Do you know how often AI models mention, cite, or recommend your crypto brand? Contact Coinpresso for a model-by-model visibility baseline.
FAQs
What is Share of Model Voice?
It's the proportion of relevant AI answers in which your brand appears relative to a defined competitor set, across a defined set of prompts. The exact formula, including which competitors and which prompts, has to be disclosed alongside the number, because the same brand can post wildly different figures depending on who's in the comparison set.
Is an AI mention the same as a citation?
No. A mention just names the brand, a citation links or attributes specific information to that brand's own source, and a recommendation goes further still by actively presenting the brand as an option worth choosing. Treating all three as one number is how a real authority problem gets disguised as a visibility win.
How many prompts should a crypto brand track?
There's no universal number, what matters is a panel large enough to cover every intent your real users actually have, from awareness through to safety and fees. Disclose the sample size and composition when you report results, and update the panel as your product and the questions around it change, the way our generative engine optimization for Web3 work approaches it for clients.
Why should ChatGPT, Gemini, and Claude be reported separately?
Because their search triggers, retrieval systems, and citation behavior genuinely aren't the same, OpenAI's own documentation describes citations that can be incomplete or outdated, while Gemini and Claude each handle grounding and sourcing through different mechanics again. Blending the three into one average hides exactly which platform has the weak spot.
Can Share of Model Voice be tied to wallet activity?
It can be compared against tagged referral and conversion data, sign-ups, wallet connections, developer activity, but that comparison shows correlation, not proof the AI visibility caused the on-chain action. Our case studies show how we build that tagging properly rather than letting a project assume causation it hasn't earned.