

A new exchange launches with better fees, a cleaner product and a security setup that would pass most audits without a hitch. Three months in, the founder types "best crypto exchange for beginners" into ChatGPT to see where they land. Coinbase gets named first, Kraken gets named second, and the platform they've spent a year building doesn't appear in the answer at all.
That gap isn't a conspiracy and it isn't unfixable. A lot of crypto marketing teams treat that silence as a brand problem when it's really an evidence problem, and it won't close by publishing more of the blog posts Coinbase and Kraken already have ten years' worth of. It closes by understanding exactly what those two platforms have built, which parts a smaller project can realistically copy, and where a narrower question exists that nobody has bothered to own yet.
Coinbase and Kraken's Combined AI Citation Share: the Numbers
One GEO research vendor's disclosed prompt panel puts Coinbase and Kraken's combined share of AI citations in crypto-exchange queries at roughly 22% for Q1 2026, with Coinbase ahead of Kraken. A second, separately run vendor panel testing similar prompts reports different shares for the same two brands. That disagreement is the first thing worth knowing about this number: it's a directional estimate from a disclosed prompt panel, not a verified industry census, and the two vendors measuring it don't agree with each other.
| What's measured | Vendor estimate | Status |
| Coinbase + Kraken combined citation share | ~22% | One disclosed prompt panel, Q1 2026 |
| Coinbase individual share | Reported differently by two separate vendor panels | Not independently verified |
| Kraken individual share | Reported differently by two separate vendor panels | Not independently verified |
Treat the 22% figure as proof the pattern exists, not as a number to build a campaign budget on. It's useful evidence that incumbents dominate generic exchange prompts. It stops being useful the moment you try to apply it to any brand smaller than the two it was built to measure.
What the 22% Figure Actually Measures
The 22% estimate comes from one GEO research firm's disclosed prompt panel, run across a defined set of consumer-intent questions on several AI platforms in a single quarter. It is not a census of every crypto query asked of every model, and the firm that produced it discloses that scope itself.
A second, independently run vendor panel testing similar questions reports noticeably different shares for the same two brands. Two vendors measuring the same two brands and landing on different numbers tells you the method is doing a lot of the work; these are modeled estimates built from a fixed prompt list and a specific time window, not a stable number anyone could reproduce exactly.
None of that makes the underlying pattern wrong. Ask any major assistant a generic "which exchange should I use" question today and Coinbase and Kraken dominate the answer far more often than their user-base numbers alone would predict. What the estimate can't tell you is why, and it can't tell a smaller project anything about which of its own narrower questions might already be winnable. That's a different kind of research, and it's the one this piece is built to do: open the actual pages these two exchanges publish, and work out what's structurally copyable from what simply isn't. Our crypto SEO work usually starts with exactly this kind of teardown, before a single page gets rewritten.
Coinbase’s Citation Moat
Coinbase's advantage starts with category association. For a huge number of people outside crypto-native circles, "Coinbase" is functionally a synonym for "the app where you buy Bitcoin," the same way "Google" became shorthand for search. Models trained on a decade of that association default to Coinbase whenever a prompt is vague enough to need a default.
Underneath that association sits a genuinely unusual evidence format: public-company disclosure. Coinbase went public via direct listing on Nasdaq in 2021, which means it files annual, periodic and current reports with the SEC as a matter of federal law, not marketing choice. Its most recent 10-K confirms Coinbase undergoes annual audits and quarterly reviews of its internal controls and reconciliation processes. That's not a security claim written by Coinbase's marketing team. It's a disclosure obligation enforced by a regulator, dated and public, sitting in a filing system models and the journalists who write about them both already trust.
Educational coverage compounds the effect. Because Coinbase has existed at scale for over a decade, there's a vast back catalog of explainers, news coverage, app-store reviews and personal-finance content that all reference it as the standard entry point to crypto. None of that content was written to game an AI model. It was written across years, for humans, for completely unrelated reasons, and that's precisely why it works as a trust signal. Volume this organic is almost impossible to manufacture on a compressed timeline.
The fourth layer is third-party repetition. Financial press, personal-finance sites and comparison tools cite Coinbase routinely enough that models encounter the same association from dozens of independent sources rather than one. A model doesn't need Coinbase to say it's trustworthy. It needs a hundred unrelated publishers to have said so already, in a hundred different contexts, over a hundred different months.
Kraken’s Different Citation Moat
Kraken's moat is built from almost the opposite material, and that's the most useful thing about studying it. It proves there is more than one route into the same answer box. Kraken, legally Payward, Inc., has operated since 2011) and was among the first crypto companies to secure a US bank charter, which buys it the same longevity signal Coinbase gets from scale, just earned through survival rather than size.
Where Kraken genuinely differentiates is proof-of-reserves. Kraken pioneered the practice in 2014 and now runs a live Proof of Reserves page showing a BTC reserve ratio of 102.9% and an ETH ratio of 100.5%. The methodology isn't a vague promise. Kraken's own engineering blog explains the page uses a Merkle tree to combine client balances, with an independent auditor confirming onchain holdings exceed what's owed, liabilities included. That's a dated, extractable, independently checkable artifact. There's nowhere for the claim to hide.
Kraken has also done something few exchanges bother with: it published its own comparison page against Coinbase, stating plainly that Kraken publishes a reserve attestation while Coinbase does not and instead points to its financial filings. That single page does double duty. It's a first-party artifact a model can cite directly, and it hands a journalist or reviewer the exact framing they need to repeat the distinction in their own words elsewhere.
The niche Kraken owns, then, isn't "best exchange" in general. It's "safest exchange" and "exchange with verifiable reserves," a narrower prompt cluster it built deliberately rather than inherited from scale.
The Five-Layer Citation-Moat Model
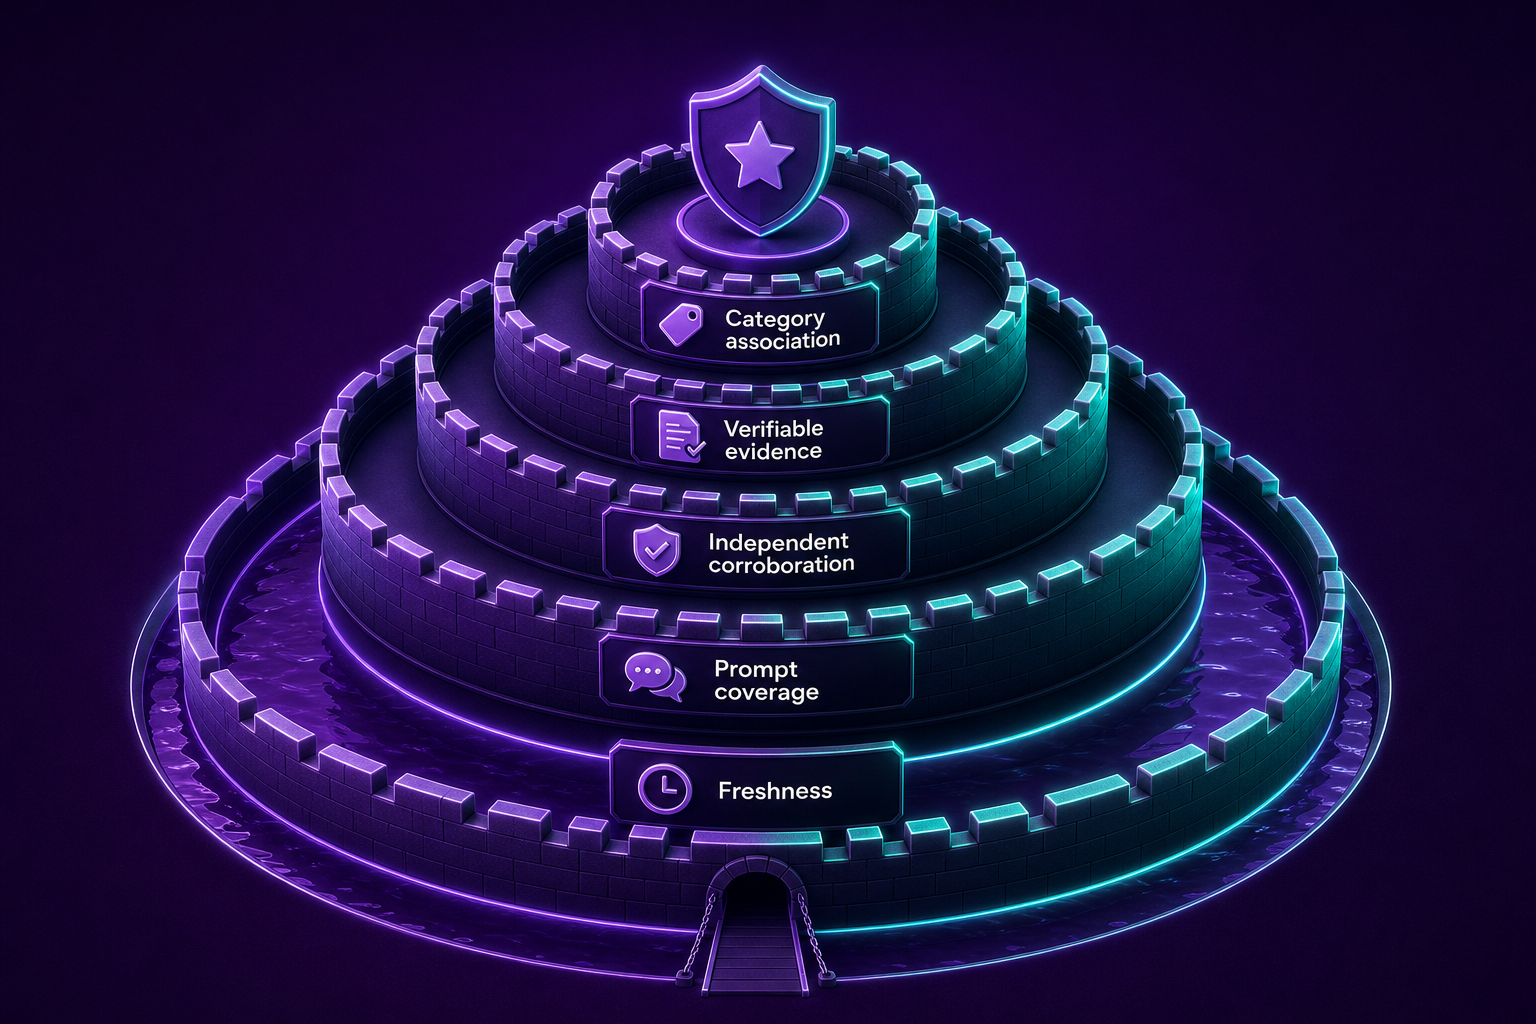
Strip away the brand names and both moats reduce to the same five layers. That's useful, because it turns the model into a checklist rather than a mystery.
| Layer | What it means | Coinbase's version | Kraken's version |
| Category association | The default a model falls back on for a vague prompt | Synonymous with "buy Bitcoin" | Longstanding exchange, bank-chartered |
| Verifiable evidence | A dated, checkable first-party claim | SEC filings, 10-K disclosures | Live Proof of Reserves page |
| Independent corroboration | Unrelated sources repeating the same claim | Decade of financial and consumer press | Security- and reserves-focused coverage |
| Prompt coverage | Which question shapes you win | Broad, generic exchange queries | Security- and reserves-specific queries |
| Freshness | How recently the evidence was updated | Quarterly and annual filing cadence | Recurring reserves republication |
Category association is the baseline recognition a model falls back on when a prompt is generic. Verifiable evidence is the first-party material a model can quote with confidence: Kraken's reserve ratios, Coinbase's SEC filings. The format differs, but the function is identical. A specific, dated, checkable claim beats a vague promise every time.
Independent corroboration is everything built on that evidence by someone who isn't the exchange itself: journalists, review sites, comparison tools, personal-finance writers. A model trusts a claim more when ten unrelated sources repeat it than when one source asserts it once, however well that source phrases it. Prompt coverage is how many distinct question shapes a brand shows up for; neither incumbent covers every prompt shape, which is the detail most competing analysis of this topic skips entirely. Freshness is whether the evidence is dated and recently updated, or sitting untouched since launch. Both incumbents stay current by design, not by accident.
A smaller project doesn't need all five layers at Coinbase's scale. It needs all five present, however modestly, for one narrow prompt cluster it actually intends to win.
What Smaller Projects Cannot Copy
Honesty matters more here than anywhere else in this piece, so it's worth being blunt. Some of what's listed above simply cannot be replicated on a six-month timeline, and no amount of clever content strategy changes that.
History is the obvious one. Kraken's founding date and Coinbase's decade-plus of consumer mindshare are facts about time passing, not facts about marketing effort. You cannot publish your way into being fifteen years old. Regulatory scale is the second: Coinbase's public-company reporting obligations exist because it's a listed company of a particular size. Chasing an equivalent disclosure volume without the underlying scale just produces padding nobody asked for.
User base is the third, and it's the one founders most often misjudge. The sheer weight of organic, unprompted mentions Coinbase and Kraken accumulate from millions of existing users isn't a content gap. It's a byproduct of having millions of users, and no publishing calendar substitutes for that. Press volume follows the same logic: a decade of being newsworthy produces a back catalog of coverage that a six-month-old project cannot manufacture by syndicating more articles faster.
The honest takeaway is that smaller projects shouldn't aim to outscale the incumbents across all five layers. They should aim to build all five layers, fully, for one prompt cluster small enough to actually own.
Find a Winnable Prompt Wedge
The mistake most smaller exchanges and tokens make is targeting the same broad prompt the giants already win. "Best crypto exchange" is Coinbase and Kraken's territory precisely because it rewards scale, history and category association, the three things a smaller project has the least of. Competing there is like opening a general store next to a hypermarket and wondering why nobody comes in.
The fix is to narrow the question until the prompt itself selects for what you actually have. That narrowing can run along several axes, and most projects only need to pick one or two:
- Use case — "best exchange for options trading" or "best platform for DCA automation" rather than "best exchange" broadly
- Chain or asset type — "best exchange for Solana memecoins" or "best platform for staking liquid-staked ETH"
- Jurisdiction — "best exchange available in [specific country]" where a major incumbent has reduced or no presence
- Audience — "best exchange for institutional treasury management" versus a retail-first positioning
- Integration — "best exchange with native support for [a specific wallet or protocol]"
- Technical capability — a specific API feature, settlement speed, or compliance workflow a larger platform hasn't built
A project offering the deepest liquidity for a specific regional fiat on-ramp doesn't need to win "best crypto exchange." It needs to win "best exchange for buying crypto with [that currency]," a prompt cluster small enough that Coinbase's scale advantage barely applies and specific enough that genuine evidence can dominate it quickly.
The test for whether a wedge is real, rather than wishful thinking, is simple. Can you point to a specific, documented, checkable advantage that answers that narrower question better than the incumbents do? If the honest answer is "not yet," the wedge isn't ready to build evidence around. If the answer is yes, the next section is how you make that advantage legible to a model. Our generative engine optimization for Web3 work starts exactly at this step, narrowing a client's target prompt before a single page gets rewritten.
Build Evidence Modules Around That Wedge
Once the wedge is chosen, the job is building first-party pages a model can quote with the same confidence it quotes Kraken's reserves page or Coinbase's filings. That means dated, extractable, specific content, structured so a fact can be lifted cleanly rather than paraphrased from a wall of prose.
In practice that means a short set of standing pages, each owning one fact category:
- A fees page stating current rates by transaction type, dated and updated on a visible cadence
- An availability page listing exactly which jurisdictions, assets and payment rails are supported, with changes logged
- A security page detailing custody arrangements, audit history and incident response, named rather than described vaguely
- An audits page linking the actual audit reports, not a summary paragraph asserting they exist
- A limitations page stating plainly what the platform does not yet support, which sounds counterintuitive but reads as exactly the kind of honest, checkable detail a model has no reason to distrust
- An eligibility page specifying who can use the platform and under what conditions, without legal hedging that obscures the actual answer
This is the same instinct behind Kraken's reserves page: a specific, dated, independently checkable claim beats a confident paragraph every time. A project doing this well treats each page the way Kraken treats its reserve ratios, as a standing artifact that gets republished and re-verified on a cycle, not a one-time blog post that quietly goes stale.
None of this guarantees a citation. What it does is remove the single most common reason a model skips a smaller brand entirely: there was simply nothing specific enough on the page to quote.
Earn Independent Repetition
First-party evidence is necessary but not sufficient. The fourth layer in the model above, independent corroboration, has to come from somewhere, and it cannot be manufactured by the project itself without the effort showing.
Earned coverage is the most durable route. A wedge-specific story, pitched to outlets that genuinely cover that niche rather than crypto broadly, produces exactly the kind of unrelated third-party repetition models weight heavily. This is the logic behind crypto earned media: a placement that exists because a journalist found the story credible is worth more, in citation terms, than ten placements the project paid to secure outright.
Reviews and directories matter for the same reason, provided they're genuine. A listing on a comparison tool or a review from an independent voice in the specific niche the wedge targets does more work than a generic crypto directory listing, because it's narrower and therefore more specific to the exact prompt being targeted. Partnerships count too, particularly where the partner is already independently trusted within the wedge's niche. A named integration partner mentioning the relationship on its own site creates a second, unrelated source repeating the same fact the project's own evidence pages already state.
Expert commentary rounds it out: a named specialist willing to go on record about the specific capability the wedge is built around gives journalists and reviewers a quotable, attributable voice, rather than an anonymous claim from the project's own marketing copy. None of this should tip into manufacturing false consensus. The goal is accurate repetition of a genuine advantage by people who have no reason to repeat it other than it being true, and that discipline is what separates earned repetition from the kind of coordinated noise that erodes trust the moment a reader looks closely.
Measurement, Conclusion, and FAQ
Publishing evidence modules and earning coverage only tells you whether the work existed, not whether it changed anything. Measurement is the step most competing guides on this topic skip entirely, and it's the one that actually proves the wedge worked.
Track four things, repeated on a cycle rather than checked once: mention rate (does the project come up at all for the target prompt, across ChatGPT, Claude, Perplexity and Gemini), citation rate (is a specific page named or quoted, rather than the project just mentioned in passing), accuracy (is what's cited still correct, given how often facts on fast-moving crypto pages go stale), and recommendation context (is the project surfacing for the narrow wedge prompt it was built for, or drifting into irrelevant broader queries where it has no real evidence advantage). Model answers vary run to run even on an identical prompt, so a single check proves little. A repeated panel over weeks is what actually shows movement.
You don't need Coinbase's decade of filings or Kraken's reserve history to win a real, narrow slice of this. You need one honest answer to a question nobody else has bothered to answer this specifically yet.
Here's the dare, and you can run it tonight without hiring anyone: open ChatGPT or Perplexity, ask the narrowest version of the question your project should win, and see whether anything you've published is specific, dated and checkable enough to be the answer. If the honest result is silence, contact Coinpresso to identify your most defensible prompt wedge and build the evidence modules that get it cited.
FAQs
Do Coinbase and Kraken really account for 22% of crypto AI citations?
That figure comes from one GEO research vendor's Q1 2026 test of more than 65 consumer-intent prompts across several AI platforms. It's a disclosed prompt panel, not a universal census of crypto queries, and a second, separately run vendor panel testing similar prompts reports different shares for the same two brands.
Why might Coinbase and Kraken appear frequently?
Both combine category association, independently verifiable evidence and years of unrelated third-party coverage into what amounts to a five-layer citation moat. Coinbase leans on scale and public-company disclosure; Kraken leans on longevity and a live, independently auditable Proof of Reserves page. Neither advantage comes from proprietary access to how any model was trained.
Can a smaller token or exchange outrank Coinbase in AI answers?
It can win narrower, better-matched prompts where it has a genuine, documented advantage, but it shouldn't expect to reproduce Coinbase or Kraken's broad recognition quickly. The realistic goal is owning a specific prompt cluster, not displacing an incumbent from the generic one.
What is a prompt wedge?
A prompt wedge is a narrower recommendation context, built around use case, chain, jurisdiction, audience or technical capability, where a smaller project has a documented, meaningful advantage and enough evidence published to support it. Coinpresso's crypto GEO case study work covers how that narrowing gets chosen in practice.
What should a project measure after publishing evidence modules?
Track prompt-specific mention rate, citation rate, accuracy and recommendation context across ChatGPT, Claude, Perplexity and Gemini, repeated over several weeks rather than checked once. If you want a second set of eyes on what's moving, Coinpresso's case studies show what that tracking looks like for real campaigns.