

Comparison pages are the most undervalued asset on a crypto marketing team's roadmap. That's a strong claim, and the obvious objection lands immediately: most of them are terrible, stuffed with affiliate links and feature tables nobody has fact-checked since launch day.
Here's the direct answer before anything else: a comparison page can shift how often a generative engine cites your project, but only when every row survives a provenance check, and nobody, including Coinpresso, can promise a specific citation rate from it. The honest way to find out is a fixed set of prompts run across ChatGPT, Perplexity and Gemini before and after you rebuild the page, which is a test worth running properly rather than guessing at here.
This piece sets out the Citation-Grade Comparison Standard for crypto generative engine optimization, a way of building "X vs Y" content that treats every row as evidence rather than decoration. It's a companion to our structural breakdown of how comparison pages get extracted, not a replacement for it.
Why Comparison Prompts Are Decision Prompts
A reader typing "Coinbase vs Kraken" into an AI model isn't browsing. They're trying to resolve a trade-off, and the answer they want names the trade-off rather than listing features side by side.
That distinction matters because not every comparison-shaped query is actually asking for a comparison. A navigation query wants the right page fast. "Coinbase fees page" is navigation dressed as a question. A research query wants raw facts laid side by side, the way someone checking withdrawal limits before moving funds does. A recommendation query is the hardest of the three, because it asks the model to weigh asymmetric facts against a stated use case: which exchange suits a UK-based DeFi trader, say.
Most crypto comparison content answers the research query reasonably well and ignores the other two entirely. A table of fees and supported assets satisfies someone doing research. It does nothing for someone who already knows the facts and wants a judgment, and it actively frustrates someone who wanted a single page and got a wall of comparison copy instead.
Building for only one of these query types is how a page becomes invisible to two-thirds of the people asking about the category. The fix isn't more content. It's structuring the same evidence so a model can answer any of the three without the page pretending to be something it isn't.
The Problem With Most Crypto “Versus” Pages
Most crypto "versus" content fails for one of four reasons, and all four produce the same result: a generative engine can't safely cite the page, or it cites it and gets something wrong. That's the real cost of a bad comparison page in 2026. It isn't lost traffic. It's reputational exposure at scale.
The first failure is affiliate bias dressed up as neutrality. A comparison page can disclose that earnings don't affect its rankings and still conclude that one exchange offers the best balance of products, fees and regulatory safety, without showing the reader the row-level evidence behind that conclusion. Disclosure is not the same thing as sourcing.
The second is hidden assumptions. A claim about "lowest fees" that doesn't state the trading tier, the payment method or the jurisdiction isn't a fact. It's a fragment of one, and a model repeating it as a universal truth is repeating something nobody actually verified.
The third is stale data presented as current. Regulatory status, fee schedules and supported jurisdictions all move, and a page with no visible effective date gives the reader no way to tell whether they're reading this morning's truth or something eighteen months old.
The fourth is false equivalence: scoring two genuinely different products on identical criteria without naming the difference between them. A centralized exchange and a self-custody wallet answer different questions, full stop. Some comparison pages are at least honest about their gaps; one openly admits it skipped verification on live account testing for at least one listing. Most don't say so at all, which is the more common and more corrosive failure.
The Citation-Grade Comparison Standard
A comparison page earns reuse by a generative engine when every factual row can survive a provenance check, not because it happens to contain a table. That's the whole standard in one sentence, and it rests on five pillars: factual symmetry, provenance, scope, uncertainty and update control.
Factual symmetry means applying the same research depth, the same units and the same level of scrutiny to both sides. Spend four hours verifying Product A's fee schedule against its own documentation, and Product B gets four hours too, not a guess lifted from a review site.
Provenance means every claim carries its source and the type of source it is. A fee figure from an exchange's own published schedule is a different grade of evidence than one from a third-party aggregator. The reader deserves to know which they're getting, and so does the model reading on the reader's behalf.
Scope means stating the conditions under which a claim is true: jurisdiction, account tier, network version, date. A true claim with no boundary on it quietly becomes a false one the moment it's read out of context.
Uncertainty means writing "not publicly disclosed" when that's the honest answer, instead of leaving a blank cell or filling it with an estimate dressed as fact. A generative engine that meets an honest gap can route around it. One that meets a confident guess has no way to tell it apart from a verified figure.
Update control is the piece most comparison pages skip entirely: a named owner, a review schedule and a trigger list for what forces an immediate correction rather than waiting for the next quarterly pass.
Here's the evidence ledger structure the rest of this article builds from, the artifact that turns a comparison page from marketing copy into something a generative engine can safely quote:
| Field | Purpose |
| Decision criterion | The specific question being answered, such as "availability in New York" or "supports deposits via SEPA" |
| Product A / Product B answer | Same unit, same depth, same scope applied to both sides |
| Source and source type | The primary URL, plus whether it's a product disclosure, an explorer, an auditor, a regulator, or independent press |
| Effective date and scope | When the information applied, and any jurisdiction, tier, chain, or version constraint |
| Limitation or uncertainty | Incomplete public data, conflicting sources, or a feature known to be in flux |
| Update trigger and owner | What change forces a re-check, and who is responsible for making it |
Nothing in this table guarantees a citation. What it buys is a page that's safe to cite, which most ranking comparison content never clears.
Build a Decision-Criterion Map
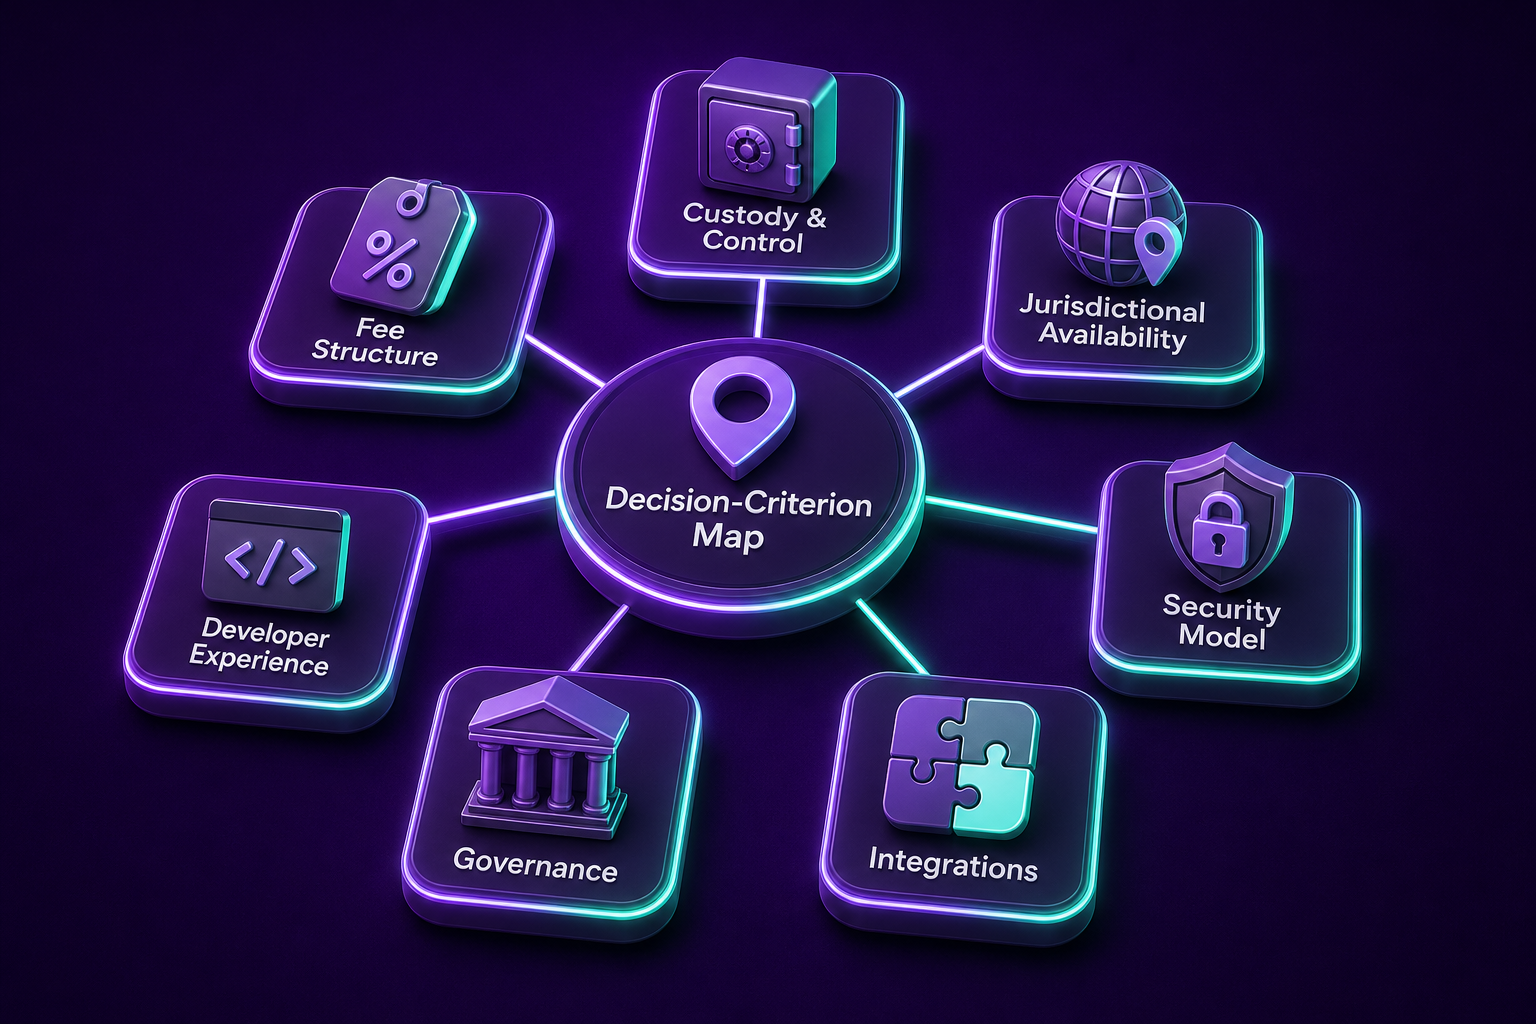
Decide which criteria actually belong to the category you're comparing before writing a single row. A generic feature list is how comparison pages end up measuring the wrong things with great precision. Custody model matters for exchanges and wallets; it's irrelevant for comparing two layer-2 rollups.
A decision-criterion map is the short list of questions a genuinely informed buyer would ask before choosing between two products, built from the category outward rather than from a template inward. For a centralized exchange comparison, that list typically runs to custody structure, fee tiers by volume, supported jurisdictions, security incident history and liquidity depth on relevant pairs.
For a DeFi protocol comparison, the list looks completely different: audit history and auditor identity, governance structure, smart contract upgrade mechanisms, integration surface with other protocols, and developer tooling maturity. Run an exchange-style map against two protocols and you get a table that looks complete and measures almost nothing a protocol user actually cares about.
The discipline is resisting the template. A reusable checklist of ten generic criteria will always be faster to produce than one built from the category's actual decision points, and it will always be weaker evidence, because several of those ten criteria won't apply cleanly to either product. Here's a working starting list, adaptable by category:
- Custody and control: who holds the keys, and under what conditions can that change
- Fee structure: by tier, by payment method, by withdrawal network
- Jurisdictional availability: where the product is licensed, restricted, or simply unavailable
- Security model: audit history, incident record, bug bounty scope
- Integrations: what the product connects to, and what that connection actually permits
- Governance: who can change the rules, and how a change gets ratified
- Developer experience: documentation quality, SDK maturity, API stability
A map built this way becomes the skeleton every row in the evidence ledger hangs off, and it's the single biggest determinant of whether the finished comparison answers the question someone was actually asking.
Source Every Claim at the Right Level
Not every source carries the same weight, and a citation-grade comparison treats sourcing as a hierarchy rather than a box to tick. A claim should be pinned to the highest tier that actually covers it.
Product documentation and published fee schedules sit at the top for anything a company controls directly: pricing, supported assets, stated jurisdictions. Audit reports and on-chain explorer records sit just below, useful for claims about contract behavior or transaction history that no amount of marketing copy can override. Regulator filings and enforcement records come next, essential for anything touching legal status. They are also the fastest-moving category in the whole ledger, so treat any date stamped on one as provisional until you've checked it's still current.
Independent press and analyst coverage sits at the bottom, useful for context and for claims no primary source has addressed, but not a substitute for one that exists. This is where stale comparison pages get caught out in public: a lawsuit's legal status is a fact with a date attached, and treating a years-old filing as current status is exactly the kind of error a sourcing hierarchy is built to prevent.
The SEC dismissed its civil enforcement action against Coinbase in February 2025, tied to the Commission's shift in crypto policy rather than a ruling on the merits. Pages still describing Coinbase as actively fighting that lawsuit are citing a fact that is simply no longer true, and the correction is a one-line check against the exchange's own current regulatory disclosures, not a research project.
It's worth looking at how a primary party handles this itself. Kraken's own published exchange comparison cites Coinbase's SEC filing obligations as 10-Q and 10-K disclosures, footnoted to the filing type rather than asserted as an unsourced claim. A competitor citing a competitor's regulatory status correctly, with the source type named, is a model worth copying regardless of who wrote it.
The practical rule is to match the source tier to the claim. A fee figure gets the fee schedule. A security incident gets the post-mortem or the audit, never a forum thread summarizing one. Where only independent press has covered something, say so in the limitation field rather than letting it masquerade as a primary citation.
Preserve Scope, Time, and Uncertainty
A fact without a boundary isn't a fact. It's a guess wearing a fact's clothing. Every row in a citation-grade comparison needs an effective date, because fees, jurisdictions and regulatory status all move, and a claim with no date attached can't be checked against anything.
Network and version matter just as much in a category where "the protocol" might mean three different contract deployments across two chains. A claim about gas costs or transaction finality that doesn't name the chain and the version is a claim about nothing in particular. Location constraints work the same way: a feature available in Singapore and blocked in New York is two different facts, not one fact with an asterisk.
Account tiers and eligibility conditions deserve identical treatment. A fee figure that only applies above a certain monthly volume, or a feature gated behind KYC verification, needs that condition stated in the row itself rather than buried in a footnote three screens down.
Where the information simply isn't public, the honest move is a label that says so, because "not publicly disclosed" is a complete and useful answer. A guess dressed as a figure is worse than a blank cell, since a blank cell at least signals that nobody is claiming to know.
Nobody gets excited writing "as of March 2026, for UK-registered accounts only" into a table cell. It's unglamorous, not difficult, and it's the sentence that makes the row trustworthy enough for a reader, or a model reading on a reader's behalf, to act on.
Establish Symmetry Without False Balance
Symmetry means identical research effort applied to both sides of a comparison, not identical conclusions. Those are different things, and conflating them is how comparison pages end up either biased or useless.
The test is simple. Spend an afternoon verifying one product's audit history against the auditor's own published report, and the competing product gets the same afternoon, not a line lifted from its marketing page. If one side's fee schedule needed three source checks to pin down, the other side gets three checks too, even when the answer turns out to be straightforward.
Genuine asymmetries exist, and a citation-grade comparison states them plainly, with evidence behind the statement rather than adjective-driven hedging. If one exchange has a documented security incident and the other doesn't, saying so isn't bias. It's the finding. The failure mode isn't naming a real difference; it's either inflating a minor one to manufacture drama, or flattening a real one into "both have their strengths" because that reads as safer.
False balance is its own kind of dishonesty. A page that gives equal column width to a well-audited protocol and one with no public audit, without stating that difference in plain terms, isn't neutral. It's withholding the one fact a reader most needs.
Commercial relationships deserve the same transparency. If a comparison includes a product Coinpresso or any other party has a paid relationship with, that belongs in the open, stated once, clearly, near the top of the page. Disclosure doesn't fix a biased methodology, but a sound methodology with disclosed interests is defensible in a way an undisclosed one never is.
Create the Update and Correction Workflow
A comparison page is a living document the day it publishes. Treating it as a one-time deliverable is how every standard above quietly decays within a quarter. The workflow needs an owner, a cadence, and trigger conditions that force action outside that cadence.
Assign a named owner for each comparison page, someone whose job includes checking it, not just whoever happened to write it originally. Set a fixed review schedule: quarterly is reasonable for most categories, tighter for anything touching fee schedules or regulatory status. Then define material-change triggers that override the schedule entirely:
- A fee schedule change on either product
- A supported-jurisdiction change, addition or removal
- A security incident or disclosed vulnerability
- A regulatory status change, enforcement action, dismissal, or settlement
- A contract migration, chain move, or major version upgrade
- A change in audit status, including a new audit or a lapsed one
Each trigger maps to an immediate edit, not a note queued for the next scheduled pass. And every substantive change needs a visible record: what changed, when, and why, kept in a changelog the reader can actually see rather than a private editing history only the team can access.
This is the part a generic GEO checklist never covers, because it isn't a content property. It's an operational one. A page can have perfect semantic headings and a flawless table and still be wrong six weeks after publication if nobody owns keeping it current.
Conclusion
An evidence-led comparison page helps three audiences in this order: the reader trying to make a decision, the search engines indexing the page, and, where a generative engine chooses to draw on it, the person who sees a synthesized answer instead of your page at all. None of those are guaranteed by following the standard above. What it buys is a page that's defensible when someone checks it, which is the actual bar in 2026, not a ranking promise.
The underlying research here is narrower than most GEO pitches imply. Academic work on generative engine optimization found that adding citations and statistics to content measurably improved how often and how prominently it appeared in generative answers, with gains running up to 37% on one metric and 22% on another depending on the strategy tested. That's evidence sourced, evidence-dense content performs better in this environment. It is not evidence that any single page format, including a comparison table, automatically wins a citation. Which sources get selected remains opaque, and it varies by model and by query.
A bad comparison page isn't just useless, it's a liability — unsourced and it's a lawsuit waiting for the first reader who checks your numbers against the primary source. Contact Coinpresso for a comparison-content evidence audit.
Fix the sourcing and the ownership first. The table formatting can wait. An unsourced claim with a beautiful layout is still an unsourced claim.
FAQs
Why are X vs Y pages useful for AI search?
They directly answer a decision problem and can present evidence in a compact, comparable format, but usefulness alone does not guarantee citation. A model still has to judge whether the page's claims are trustworthy enough to repeat, which is exactly what the Citation-Grade Comparison Standard above is built to prove.
How is this different from a standard product comparison table?
The difference is governance: each claim has a source, date, scope, limitation and update owner rather than an unattributed feature tick. Our structural breakdown of comparison pages covers the layout and extraction side; this standard covers whether what's inside that layout is actually true.
Should a crypto comparison page be neutral?
It should be factually symmetrical and disclose commercial interests. A recommendation can still be made when it is tied to a stated use case and evidence, rather than hidden behind vague claims of impartiality.
How frequently should a comparison page be updated?
Review on a fixed schedule and immediately after material changes to fees, supported jurisdictions, security incidents, product availability, contract migrations, or regulatory status. The dismissal of the SEC's case against Coinbase is a textbook example of the kind of update that can't wait for the next quarterly pass.
Can a project compare itself with a competitor?
Yes, provided the methodology, commercial relationship, source evidence, and limitations are clear, and competitors receive equivalent factual treatment. If you want a second set of eyes on whether your own comparison content clears that bar, our case studies show how that kind of audit plays out in practice.